Managing Clusters using ClusterControl MCP
In this section, we explore how to manage your database clusters using natural language through the ClusterControl MCP Server. Instead of navigating dashboards or running CLI commands, you simply describe what you want to your AI assistant and it handles the rest.
If you haven't set up the ClusterControl MCP Server yet, please go through the ClusterControl MCP documentation first before continuing.
If you have already installed and integrated it with your AI assistant, make sure the integration is working properly before proceeding. For example, if you are using Claude Desktop, go to Settings → Developer and confirm that the ClusterControl MCP is listed and running. See screenshot below
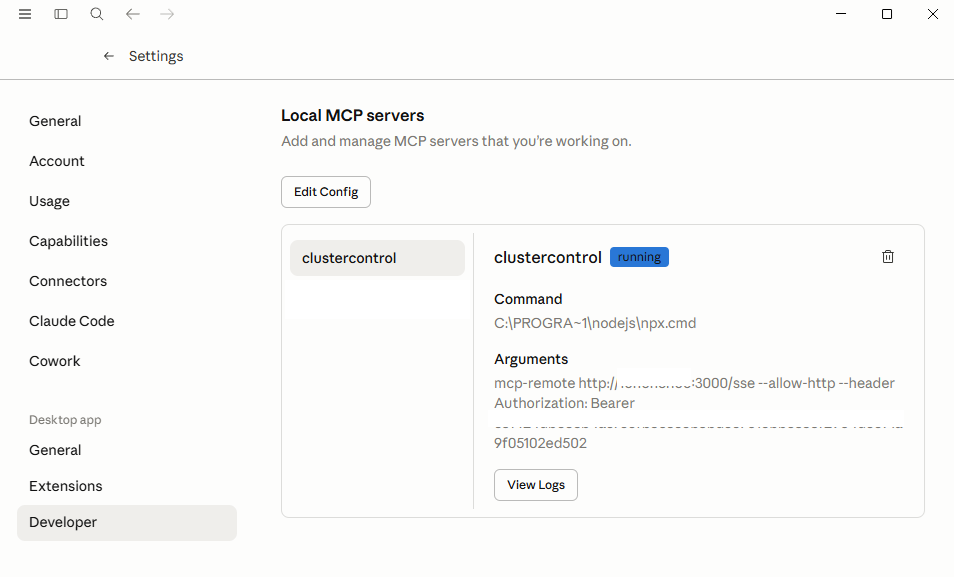
Once you can see the MCP Server is running, you are ready to start managing your clusters. The examples below cover the most common operations you can perform through your AI assistant.
Any action that changes something like creating a job, adding a user, scheduling maintenance, restoring a backup, setting node or controller config, etc. Works in two steps:
-
Dry run (default): AI Assistants describes exactly what it would do, without touching your CMON controller.
-
Execute: After you confirm, AI Assistants calls the tool again with dry_run=false to carry out the action.
High-risk operations (node restart, failover, drop cluster, drop user, delete backup schedule, restore backup, delete ClusterControl account) are marked with a destructiveHint annotation and include an additional warning in the dry-run output. MCP clients can use these hints to require your explicit confirmation before running such operations — but this safeguard depends on the client honoring the hints and the dry-run flow; the annotations are advisory metadata, not server-side enforcement. The server can also enforce this itself: with the execution guard and the approval tier switched on, a destructive call runs only after a preview of the same call and an approval. See Confirmation and Approval.
User and Access Management
Manage database accounts, review privileges, create or revoke access across your clusters.
List Functions
Below are the functions that currently supported by clustercontrol-mcp for User and Access Management.
| Function | Purpose |
|---|---|
list_db_users |
List all database accounts on a cluster (Required Cluster ID) |
create_db_user |
Create a new database user account (Required Cluster ID) |
drop_db_user |
Delete a database user account (Required Cluster ID) |
grant_db_user |
Grant privileges to a database user (Required Cluster ID) |
revoke_db_user |
Revoke specific privileges from a database user (Required Cluster ID) |
revoke_all_db_user |
Revoke all privileges from a database user (Required Cluster ID) |
list_cmon_users |
List all ClusterControl controller user accounts (Required Cluster ID) |
list_cmon_groups |
List all ClusterControl controller user groups (Required Cluster ID) |
create_cmon_user |
Create a new ClusterControl controller user account (Required Cluster ID) |
set_cmon_user |
Modify a ClusterControl controller user profile (Required Cluster ID) |
drop_cmon_user |
Delete a ClusterControl controller user account (Required Cluster ID) |
Example Prompt
Here are some examples of using clustercontrol-mcp for User and Access Management:
-
List existing users and groups using prompt
List all users and groups that exists in clustercontrol and mask the email

-
Create ClusterControl user and attach to group using prompt
Create a Clustercontrol user with username support and email [email protected] using password severalNINES999 in group admins

Cluster Inventory and Health
Get a complete picture of your clusters, nodes, topology, and active alarms.
List Functions
| Function | Purpose |
|---|---|
list_clusters |
Full fleet overview with cluster types, states, and versions |
get_cluster |
Detailed view of a specific cluster including all hosts and their roles (Required Cluster ID) |
get_cluster_topology |
Normalized topology view showing nodes and replication links (Required Cluster ID) |
list_nodes |
Flattened node inventory across all clusters or one cluster (Optional Cluster ID) |
list_alarms |
Active alarms for a specific cluster (Required Cluster ID) |
list_all_alarms |
Active alarms across the entire fleet |
get_controller_info |
CMON version, RPC version, and connectivity status |
get_cluster_log |
Contents of one collected log file, addressed by (cluster_id, hostname, filename). Read-only; returns the tail of the last 200 lines by default, with optional max_bytes, port, and tail_lines parameters (Required Cluster ID) |
export_cluster_log |
Writes the full contents of one collected log file to a local output_path on the MCP Server host; the file is created with mode 0600 (Required Cluster ID) |
get_cmon_logs |
CMON daemon log entries for a cluster. New optional filters: severity, component, hostname, since |
get_cmon_log_statistics |
Summary counts of CMON log entries by severity and component |
list_cluster_logs |
Inventory of log files CMON has collected from cluster hosts (mysqld.log, postgresql-*.log, prometheus.log, agent_internal_logs.log, cmnd.log) |
Example Prompt
Here are some examples of using clustercontrol-mcp for Cluster Inventory and Health:
-
Get information about Cluster databases
List all database clusters
Get details for cluster
cluster_idorcluster_nameGet the logs for cluster
cluster_idorcluster_nameList active alarms for cluster
cluster_idorcluster_name


Tips
On a large installation, ask for a number of items at a time, for example "list the first 20 alarms".
The list tools take a limit, and a page that leaves items out ends with a cursor the assistant
passes back to read the rest.
Performance Analysis
Identify slow queries, long-running transactions, deadlocks, and other performance bottlenecks across your database fleet.
List Functions
| Function | Purpose |
|---|---|
get_cluster_stats |
Time-series CPU, memory, disk, network, SQL, and DB stats (Required Cluster ID) |
get_top_queries |
Top resource-consuming query digests (Required Cluster ID) |
get_sql_processes |
Live process list across all nodes (Required Cluster ID) |
kill_db_process |
Terminate runaway queries (Required Cluster ID) |
get_db_growth |
Historical database size trends for capacity planning (Required Cluster ID) |
check_no_primary_keys |
Find tables missing a primary key (Required Cluster ID) |
check_redundant_indexes |
Find redundant indexes (Required Cluster ID) |
check_myisam_tables |
Find tables using the MyISAM storage engine (Required Cluster ID) |
get_tx_deadlocks |
Transaction deadlock analysis with blocking SQL |
Example Prompt
Here are some examples of using clustercontrol-mcp for Performance Analysis:
-
Show current processlist from the cluster.
Show currently running SQL queries on cluster mariasn (mariadb)

-
Kill the running job
Kill the query with pid #14927

Jobs and Operations
Monitor running and completed jobs, track task progress, and review operational history across your clusters.
List Functions
| Function | Purpose |
|---|---|
list_jobs |
Recent jobs with optional status and command filters (Required Cluster ID) |
get_job_log |
Full log output for a specific job (Required Cluster ID and Job id) |
create_job |
Trigger backup, restart, failover, and other cluster operations (Required Cluster ID and command string) |
kill_job |
Terminate stuck jobs (Required Job ID) |
Galera clusters with a node down
While a Galera node is down, the MCP Server refuses the actions that would let ClusterControl's own
recovery choose which node to bootstrap from: turning automatic recovery on, ending a cluster-wide
maintenance window while it is on, killing a job that holds the cluster in maintenance (such as a
restore, an upgrade or a rolling restart), and a forced cluster removal while such a job runs. A
Galera start without a named donor is always refused. To bring back a cluster whose every node is
down, use the sop_galera_recovery procedure below.
Example Prompt
Here are some examples of using clustercontrol-mcp for Jobs and Operations:
List recent jobs on cluster
cluster_idorcluster_nameShow log for job
job_idon clustercluster_idorcluster_name
Backups and Scheduling
Manage backup jobs, review backup history, create schedules, and restore from existing backups.
List Functions
| Function | Purpose |
|---|---|
list_backups |
Recent backups with status and method filters (Required Cluster ID) |
get_latest_backup |
Most recent backup, optionally only successful ones (Required Cluster ID) |
list_backup_schedules |
View all configured backup schedules (Required Cluster ID) |
get_backup_schedule_summary |
Summary of backup schedules for a cluster (Required Cluster ID) |
create_backup_schedule |
Create a new recurring backup schedule (Required Cluster ID) |
update_backup_schedule |
Update an existing backup schedule (Required Cluster ID) |
delete_backup_schedule |
Delete a backup schedule (Required Cluster ID) |
delete_backup |
Delete a backup record (Required Cluster ID) |
restore_backup |
Restore from an existing backup (Required Cluster ID) |
Example Prompt
Here are some examples of using clustercontrol-mcp for Backups and Scheduling:
When was the last successful backup on cluster
cluster_idorcluster_name?Create a MariaDB backup schedule on cluster
cluster_idorcluster_nameevery day at 4:25 AM using the mariabackup(full) backup method.
Tips
To successfully create a backup schedule, please mention the exact backup method name that you want to use, for example mariabackup(full) for a full backup. If you only mention use mariabackup method, the backup schedule job will be created but it will fail because the backup method is not recognized by ClusterControl.
ProxySQL
Inspect and manage ProxySQL instances including backend servers, query routing rules, and traffic statistics.
List Functions
| Function | Purpose |
|---|---|
list_proxysql_top_queries |
Top queries by execution time through the proxy (Required Cluster ID) |
list_proxysql_rules |
Query routing rules (Required Cluster ID) |
list_proxysql_servers |
Backend server health and hostgroup configuration (Required Cluster ID) |
Example Prompt
Here are some examples of using clustercontrol-mcp for ProxySQL :
List ProxySQL backend servers on cluster
cluster_idorcluster_nameList ProxySQL query routing rules on cluster
cluster_idorcluster_nameShow top queries through ProxySQL on cluster
cluster_idorcluster_name
Configuration
View and modify configuration parameters at the cluster, node, and controller level.
List Functions
| Function | Purpose |
|---|---|
get_cluster_config |
View cluster-level database settings, optionally only the names you list (Required Cluster ID) |
get_node_config |
View node-level database settings, optionally only the names you list (Required Cluster ID and Node) |
set_node_config |
Modify a node configuration parameter (with dry-run safety) (Required Cluster ID and Node) |
unset_node_config |
Reset a node configuration parameter to default (with dry-run safety) (Required Cluster ID and Node) |
get_controller_config |
View CMON controller runtime parameters; by default only those that differ from their default (Required Cluster ID) |
set_controller_config |
Modify CMON controller runtime parameters (with dry-run safety) (Required Cluster ID) |
Example Prompt
Here are some examples of using clustercontrol-mcp for Configuration :
Get configuration for node [node] on cluster
cluster_idorcluster_nameSet
max_connectionsto150on node [node] in clustercluster_idorcluster_nameReset
max_connectionsto default on node [node] in clustercluster_idorcluster_nameWhich controller settings on cluster
cluster_idorcluster_namediffer from their defaults?
Tips
get_controller_config lists only the settings that differ from their default, and ends with a line
counting what it left out. Ask for all settings, or with descriptions, to see the rest. The
names filter takes names or wildcards such as *backup*.
Advisors and Findings
Ask for findings rather than raw data. Each advisor inspects a cluster and reports what is wrong or risky as machine-readable findings, each naming its cluster and, where it can, what to run next. Missing or stale data is reported as unknown, never as clean.
List Functions
| Function | Purpose |
|---|---|
advise_replication_topology |
Broken replication links, lagging replicas and single-node primaries |
advise_failover_readiness |
Whether ClusterControl could fail over now, and to which replica or standby |
advise_backup_posture |
Whether the backups will restore and the recovery point is met |
advise_workload |
Query hotspots, likely full scans, long-running and idle-in-transaction sessions, recent lock waits |
advise_galera_health |
Whether a Galera cluster is whole, in sync and keeping up: partitions, nodes not synced, flow control |
audit_db_privileges |
Database accounts with over-broad privileges |
check_config_drift |
Configuration that differs between the nodes of a cluster |
check_ssl_posture |
Whether SSL is actually enabled on the database servers |
check_version_eol |
Database releases at or past end of support |
check_capacity |
Which database host fills its disk first, and when at its recent growth |
get_fleet_posture |
Runs eight advisors over every cluster you can read and ranks the findings, worst cluster first |
get_fleet_digest |
What changed across every cluster you can read since a time you give: new and cleared findings, alarms, failed jobs |
Example Prompt
Here are some examples of using clustercontrol-mcp for advisors and findings:
Which of my clusters need attention first, and why?
Is replication healthy on cluster
cluster_idorcluster_name?Will my backups on cluster
cluster_idorcluster_namerestore?What in the workload on cluster
cluster_idorcluster_nameneeds attention?Is my Galera cluster
cluster_idorcluster_namein sync?When will the disks on cluster
cluster_idorcluster_namefill up?What changed across my clusters since 18:00 yesterday?
Which of my database releases are out of support?
The Fleet View
get_fleet_posture answers "which clusters need attention first, and why?" by running eight advisors
over every cluster you can read. An advisor that does not take a cluster's engine is listed for that
cluster as not_applicable, never as healthy.
| Advisor | Runs on |
|---|---|
advise_replication_topology |
MySQL replication and single-node MySQL, Galera (redundancy only), and POSTGRESQL_SINGLE |
advise_failover_readiness |
Oracle MySQL and Percona replication, and community PostgreSQL 14 to 18 POSTGRESQL_SINGLE |
advise_backup_posture |
Every engine |
check_ssl_posture |
Every engine's database nodes, as ClusterControl classifies them |
check_version_eol |
Every engine; a vendor or release the bundled lifecycle table does not list is reported as unknown |
check_capacity |
Every engine's database nodes, as ClusterControl classifies them |
advise_workload |
MySQL-family clusters (replication, single-node, Galera, group replication), and POSTGRESQL_SINGLE from its process list only |
advise_galera_health |
Galera clusters of Percona XtraDB Cluster 8.0 and 8.4 and MariaDB Galera 10.11 and 11.4 |
- Unknown is never clean. A cluster whose data could not be read, or is stale, counts as unknown.
Workload data the server could not judge stays visible as
WORKLOAD_DATA_UNAVAILABLE, an info finding counted once as unknown. On PostgreSQL the query digests and lock waits are always reported that way, because the server does not read them there. - A call has a 45-second budget. What is still running when it runs out is cut and what has not started is skipped as out of time, with the findings already read kept. A Galera cluster takes at least 5 seconds to assess, because flow control is judged from two reads 5 seconds apart.
- The load on the controller is bounded. A call reads four clusters at a time, and every fleet call the server serves, from any identity, shares eight concurrent controller requests, at most four of them for one identity. A call that finds them all in use waits, spending its own budget. This bounds how many requests run at once, not how many a call makes in total.
- Large fleets come in pages. The answer holds at most 50 findings and 64 KiB of text. When clusters are cut, or left incomplete by the budget, it ends with a cursor, and the next call assesses the clusters no earlier page returned.
get_fleet_digest uses the same eight advisors to report what changed. It needs a since within the
last 72 hours. New and cleared findings are reported against the baseline an earlier digest captured:
pass the next_since a completed digest returned as the next call's since, for example each evening
and again each morning. Baselines live in the server's memory, so a restart loses them, and a missing
baseline or source is reported as unknown, never as cleared. Backup misses are always unknown in this
release.
Guided Procedures
Guided procedures are MCP prompts that walk the AI assistant through a task step by step. Each procedure that changes a cluster checks that the cluster is eligible, previews before it acts, asks for approval, and stops for a person when something is off. It ends with one verdict line, VERDICT_SUCCESS, VERDICT_FAILURE or VERDICT_UNKNOWN, from a read the assistant runs again at the end. sop_daily_review only reads.
List Functions
| Procedure | Purpose |
|---|---|
sop_rebuild_replica |
Rebuild a MySQL-family replica whose replication link is down |
sop_rebuild_standby |
Rebuild a PostgreSQL 14 to 18 standby that cannot follow its primary |
sop_backup_verify |
Prove a MySQL-family backup restores, onto a spare host a person chooses |
sop_backup_verify_postgresql |
Prove a PostgreSQL pg_basebackup or pgdumpall backup restores |
sop_failover_drill |
Rehearse a failover: switch a MySQL replication primary over to a chosen replica. A PostgreSQL cluster is routed to sop_failover_drill_postgresql |
sop_failover_drill_postgresql |
Rehearse a failover on a PostgreSQL 14 to 18 cluster, to the standby the failover advisor chooses |
sop_switchover_postgresql |
Switch a PostgreSQL 14 to 18 primary over to a caught-up standby |
sop_galera_recovery |
Bring back a Galera cluster whose every node is down, from its most advanced node, with a person confirming each host is shut down |
sop_minor_upgrade |
Apply the newest minor release to a MySQL replication or Galera cluster |
sop_minor_upgrade_postgresql |
Apply the newest minor release to a PostgreSQL 14 to 18 cluster |
sop_major_upgrade |
Upgrade a cluster to a new major version |
sop_pitr_restore |
Restore a cluster to a point in time from one of its own backups |
sop_daily_review |
Collect what changed, the active alarms and the fleet view into one paste-ready summary; read-only, with nothing to approve |
Example Prompt
Here are some examples of using clustercontrol-mcp guided procedures:
Rebuild the broken replica on cluster
cluster_idorcluster_nameProve that the latest backup of cluster
cluster_idorcluster_namerestoresSwitch cluster
cluster_idorcluster_nameover to its standbyRun a failover drill on PostgreSQL cluster
cluster_idorcluster_nameEvery node of Galera cluster
cluster_idorcluster_nameis down. Recover it.Restore cluster
cluster_idorcluster_nameto how it was at 10:00 this morningGive me the daily review since 18:00 yesterday
Note
Whether the server itself enforces the preview and the approval depends on its settings. See Confirmation and Approval.
Incident Triage, Upgrades and More
List Functions
| Function | Purpose |
|---|---|
get_incident_bundle |
Gather the context of an incident on a cluster in one call; it can be anchored on a job |
get_job_checkpoint |
Where a job stopped, and what it was doing when it did |
list_available_upgrades |
The package upgrades the controller last found for each host |
export_terraform |
Export a cluster as Terraform for the ClusterControl provider |
search_docs |
Search the ClusterControl documentation installed with the MCP Server, without network access |
get_session_info |
Which ClusterControl user this session acts as, its transport, the deployment profile, the controller's version, and whether approvals can reach it |
summarize_agent_activity |
What agents asked to do over an interval, from the server's own audit log: calls, previews, execution requests, refusals and approval decisions |
Example Prompt
Something is wrong with cluster
cluster_idorcluster_name. Gather what you need to triage it.Where did job
job_idget to? Is it safe to move on?Which package upgrades are waiting on cluster
cluster_idorcluster_name?How do I configure backup retention in ClusterControl?
What did you ask ClusterControl to do between 09:00 and 17:00 today, and was anything refused?
Note
summarize_agent_activity reads the MCP Server's audit log, so auditing must be on, and it is not
in either deployment profile's allow list. Each identity sees its own activity; see
Agent Activity.
Maintenance, Audit, and Other Tools
Schedule maintenance windows, review audit logs, generate error reports, and perform other administrative tasks.
List Functions
| Function | Purpose |
|---|---|
list_maintenance |
List maintenance windows for a cluster (Required Cluster ID) |
list_all_maintenance |
List maintenance windows across all clusters (Required Cluster ID) |
add_maintenance_window |
Schedule a maintenance window for a host (Required Cluster ID) |
remove_maintenance_window |
Remove a maintenance window by UUID (Required Cluster ID) |
remove_maintenance_windows_by_filter |
Bulk remove maintenance windows by cluster or hostname (Required Cluster ID) |
list_audit_log |
Who did what, when, and from where (Required Cluster ID) |
acknowledge_alarm |
Acknowledge a single alarm (Required Cluster ID) |
acknowledge_alarms_by_filter |
Bulk acknowledge alarms by cluster or filter (Required Cluster ID) |
list_schemas |
List all database schemas on a cluster (Required Cluster ID) |
create_schema |
Create a new database schema (Required Cluster ID) |
list_publications |
PostgreSQL logical replication publications (Required Cluster ID) |
list_subscriptions |
PostgreSQL logical replication subscriptions (Required Cluster ID) |
list_error_reports |
List generated error reports for a cluster (Required Cluster ID) |
generate_error_report |
Generate a new error report (Required Cluster ID) |
download_error_report |
Download a generated error report archive (Required Cluster ID) |
unpack_error_report |
Extract a downloaded error report archive (Required Cluster ID) |
Example Prompt
Here are some examples of using clustercontrol-mcp for Maintenance, Audit, and Other Tools :
Show audit logs across all clusters
List error reports for cluster
cluster_idorcluster_nameGenerate an error report for cluster
cluster_idorcluster_name
Tips
The download_error_report tool will download the error report to the host where clustercontrol-mcp is installed. When using the AI Assistant, you are not restricted to English, feel free to use your local language. You can also create your own custom prompts tailored to your specific needs, and integrate ClusterControl MCP with any automation tools you already have.
Attention
Please use ClusterControl MCP with AI Assistants wisely and be cautious about the information you share with them. Avoid sharing sensitive or confidential data such as API keys, or any personal information. ClusterControl MCP is designed to simplify the management of clusters maintained by ClusterControl, with a scope limited to ClusterControl-related operations only.